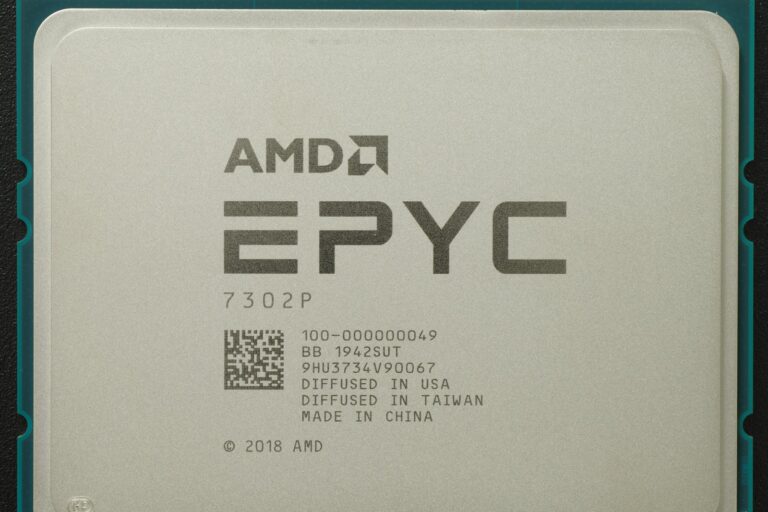
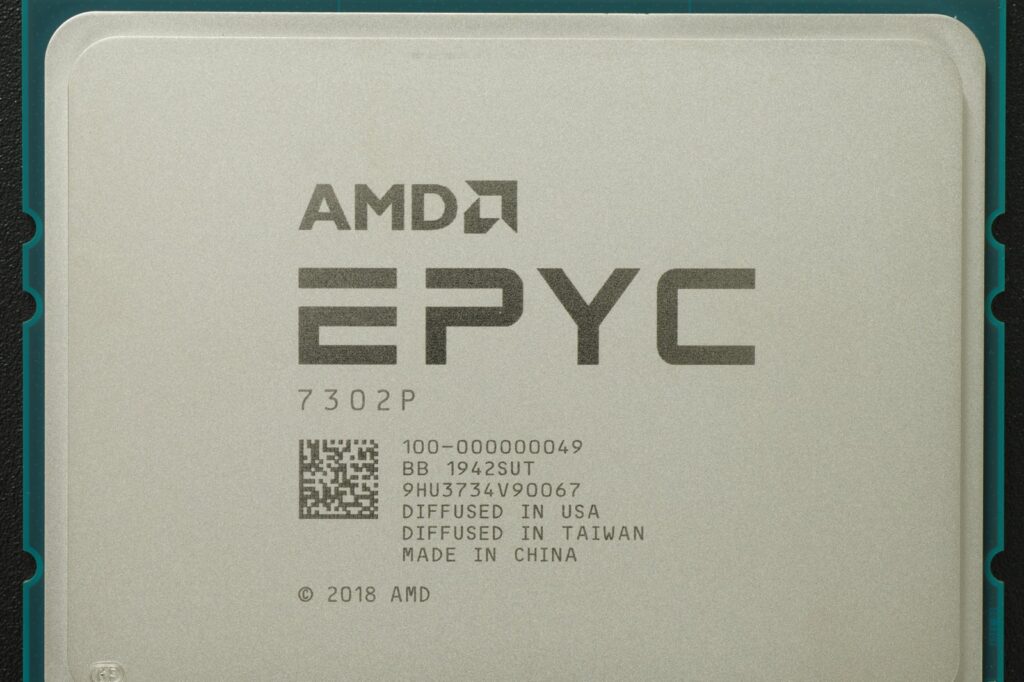
SANTA CLARA, November 11, 2026 — AMD has begun shipping 6th Gen EPYC SP7 processors based on the new Zen 6 architecture, marking the first time a server CPU debuts the company’s latest microarchitecture before consumer products. The Venice platform targets the exploding demand for server CPUs that can both host accelerated infrastructure and run agentic AI workloads natively.
The Shift Is Memory Bandwidth And Native FP16
The architectural changes in Zen 6 are built around feeding data to cores faster and handling AI math directly. The SP7 platform moves to 16 memory channels, doubling the bandwidth available to the CPU complex compared to the previous generation. At the same time, AMD split the single I/O die into two separate IODs to manage that memory subsystem, a trade-off that reduces available PCIe 6.0 lanes compared to the SP8 platform but unlocks the bandwidth local LLM inference demands.
Inside the core, the vector engine has been redesigned to natively execute half-precision FP16 instructions alongside standard 32-bit precision. This is a critical shift for inference workloads that rely on reduced precision; previously, x86 cores had to emulate or convert FP16, adding latency. The integer schedulers have also been split within the execution engine, allowing more instructions in flight per cycle. TSMC’s N2P process node underpins these changes, enabling clocks up to 5.3 GHz and instruction-per-clock gains of 20 to 31 percent depending on the workload.
Core Density Scales To New Heights
AMD has restructured its chiplet strategy for the first time since Zen 3. A standard Zen 6 CCD now scales up to 12 cores, while the dense Zen 6c CCD packs 32 cores — double the 16-core limit of Zen 5c. For the 6c variant, AMD also doubled the shared L3 cache per core, effectively quadrupling the total L3 available on the die compared to the previous dense generation. The flagship EPYC 9996 utilizes these dense chiplets to reach 256 cores per socket, delivering 1,024 threads in a dual-socket configuration.
Benchmarks: Venice Versus Vera
The frequency-optimized EPYC 9686F serves as AMD’s direct answer to Nvidia’s Vera CPU for workloads like scientific computing, HPC, and LLM inference. In testing, the 9686F outclasses Vera in specific benchmarks, while the dual-socket 9996 configuration delivers up to a 93 percent performance gain generation-on-generation in SPEC CPU 2026 intrate throughput against the prior 768-thread EPYC 9965 platform. Intel’s Granite Rapids-AP is described as rarely entering the conversation at this performance tier, though Diamond Rapids is expected next year to shift the competitive landscape.
Cloud Adoption And The Host CPU Role
Microsoft Azure and Oracle Cloud Infrastructure have announced upcoming general availability of instances powered by 6th Gen EPYC, targeting agent orchestration, concurrent agent sandboxes, and enterprise applications. The launch extends a proven pattern: 5th Gen EPYC processors currently power the host infrastructure for Google Cloud’s TPU 8tx, managing workload orchestration, data preparation, and high-throughput communication with the accelerators while providing hardware-enforced confidential computing via AMD SEV. The Venice generation aims to consolidate that host role while adding the muscle to run inference and agentic workloads on the CPU itself.
Market Position: Undisputed Leadership
AMD states its ambition is to become the undisputed market leader for server CPUs with this launch. The Venice portfolio spans multiple families, including the return of high-cache Venice-X parts and the forthcoming LPDDR5X-based Verano platform expected next year, which will further target accelerator-feeding duties. For now, 6th Gen EPYC SP7 platforms are shipping from leading OEMs and ODMs, and the silicon is in the cloud providers’ hands.
Sources
- AMD Showcases 6th Gen AMD EPYC Processors to Lead Next Era of AI and Enterprise Computing
- Epyc
- AMD's Epyc X-chips are back after a three-year hiatus
- AMD Zen 6 EPYC ‘Venice’ deep dive and benchmarking – 9686F outclasses Nvidia’s Vera, dual EPYC 9996 with 1,024 threads delivers up to 93% performance gain gen-on-gen
- AMD EPYC processors power Google Cloud’s confidential AI – Engineering.com
- AMD EPYC 9006 Results Are Here and AMD Delivers a Knockout Part Deux
Photo: Smial (talk) (FAL)